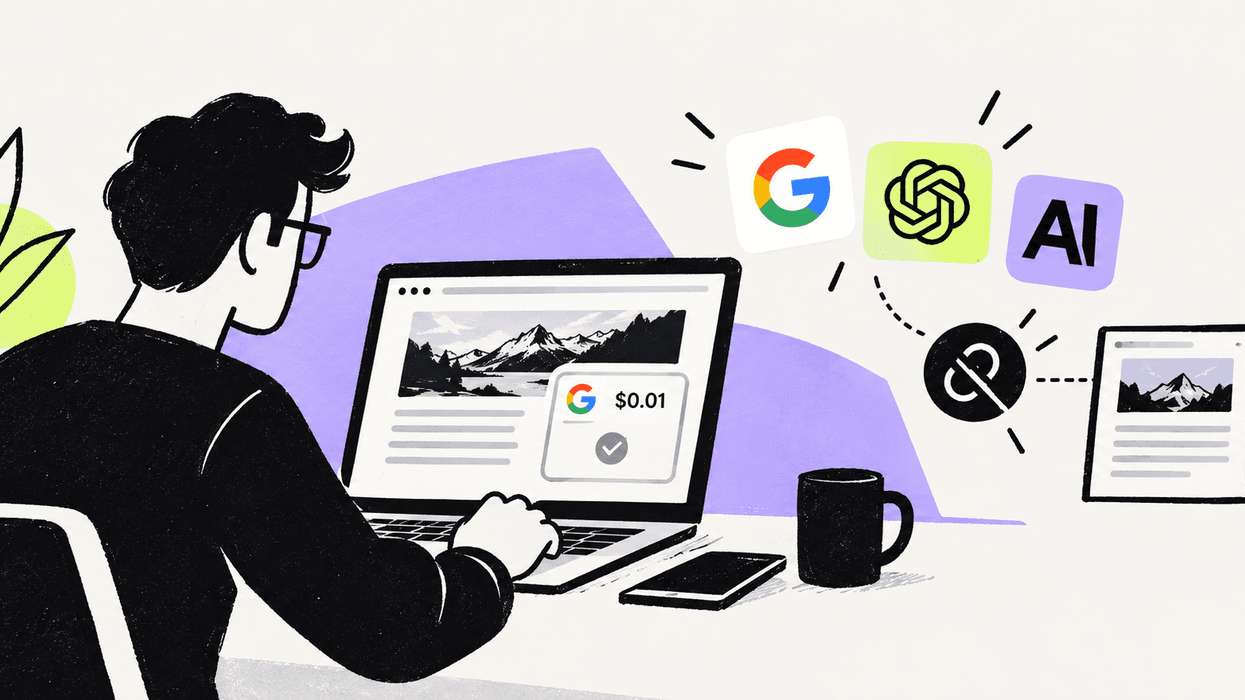
A developer wanted to know if an AI agent would actually pay for a web page instead of just taking it, so he built a tollbooth. Using the open-source x402 payment protocol, Suganthan Mohanadasan set up his site to charge one cent per page, gave a Claude agent a small spending budget, and watched it complete real transactions on testnet without a person approving each one. It worked! The agent paid and nobody had to ask for permission first.
That's one experiment. The reason it matters is that the same week, three of the largest platforms on the internet rolled out their own versions of the same idea, and they don't agree on how it should work.
Three Companies With Three Very Different Deals
Google, Cloudflare, and Microsoft each shipped a compensation model for AI content use within days of each other, and the differences are the whole story. Google's pilot pays publishers when their content makes a "significant contribution" to an AI response, a judgment Google makes itself, with no visibility into the calculation. Cloudflare's Pay Per Crawl lets a publisher set a price per fetch and get paid on that publisher's own terms. Microsoft's marketplace goes further still, letting publishers define their own licensing and usage terms with reporting attached.
Read those three next to each other and there’s one thing that jumps out. Only one of them puts the publisher in control of the number. A pilot that pays you based on someone else's private math isn't much of a negotiation.
Blocking Was Never the Whole Answer
Governance got easier this month, too, and that's worth separating from the payment question. Cloudflare's Bot Preference Sync now auto-generates robots.txt entries from three broad categories: search, agent, and training. Most sites' stated crawler policy and their enforced one don't actually match, and that mismatch is a real problem that the feature solves. The catch is that broad categories can't make the per-crawler calls a lot of sites actually need, and a feature that's on by default risks publishing a policy nobody at the company chose on purpose.
A separate Cloudflare setting now blocks AI training specifically while carving out an exception for Google, Bing, and Apple's search crawlers. That carve-out quietly reveals the assumption baked into the whole system. Search crawling is still assumed to be worth allowing for free, because it sends traffic back to you. Training and answer-generation are the parts publishers are starting to price separately, because those don't send anything back at all.
We built our crawler governance approach around that distinction. Our robots.txt guide walks through setting per-crawler rules rather than a blanket allow or block, which is the same principle behind Cloudflare's category system, just with more room for a publisher to make specific calls instead of accepting three broad buckets someone else defined.
Why an Agent Would Even Bother Paying
It's worth pausing on why this works at all. An AI agent acting on someone's behalf doesn't have pride, or a habit of skipping the paywall out of spite. It has a budget and a task. If the fastest, cheapest path to a good answer runs through a page that costs one cent, and the alternative is scraping five lower-quality free pages and hoping the synthesis holds up, a well-built agent takes the cent every time. Price becomes a quality signal in a system that otherwise has none.
That's a strange inversion of how the free web has worked. A paywall used to mean fewer readers. For an agent with a budget and no ego, a reasonable price might mean more trust, not less, because someone bothered to put a number on the content instead of giving it away to everyone, including the crawlers training a competitor's model. Small? Yes. But the incentive runs the opposite direction from what three decades of web economics trained publishers to expect.
The Part That Still Needs a Person
None of this is fully live yet. Major AI crawlers mostly don't support payment protocols today, and testnet transactions aren't the same as a production revenue line. But the direction is clear enough that waiting for it to become mandatory is a choice, not neutral inaction.
Here's what a script can't decide for you: which content is worth gating at all. An AI agent doesn't care whether a page is a thousand-word explainer or a proprietary dataset that took a research team six months to build. It just requests the page. A publisher has to make that call, page by page or category by category, based on what the content actually costs to produce and what it's worth to whoever's asking. That's a judgment about your own business, not a technical setting. The same goes for pricing. A penny per page might be generous for commodity content and insulting for the kind of reporting nobody else has. Getting that number right requires knowing your own catalog, which no crawler, however well configured, can do for you.
This is also where the "three different deals" problem stops being abstract. Choosing Cloudflare's model over Google's pilot, or negotiating Microsoft-style terms directly, is a strategic decision about how much control you're willing to trade for how much simplicity. Nobody should let a default setting make that decision.
Where to Start Without Waiting for the Standard to Settle
A few moves make sense regardless of which payment model eventually wins:
- Separate your crawler policy from your training policy. They're different questions with different answers. A page you're happy to have crawled for search can still be a page you don't want feeding a model's training run, and vice versa.
- Audit what's actually gate-worthy before a payment rail forces the question. Original research, proprietary data, and long-form reporting are the categories worth pricing deliberately. Most evergreen explainer content probably isn't, and treating everything as equally valuable just slows down the decision that matters.
- Review your robots.txt like it's a real policy document, not a default. If a platform can auto-generate entries on your behalf, someone at your organization should still be reading what it wrote before it goes live, the same way you'd review a contract someone else drafted for you.
What a Publisher Can Actually Do Now
- Give away freely.
- Meter cautiously.
- Never hand over without a negotiated license.
Most sites will find the first pile is enormous and the third pile is small. That's fine. The exercise isn't about gating everything. It's about knowing, in advance, which handful of pages you'd actually fight for if a crawler showed up asking.
That kind of groundwork doesn't require picking Cloudflare over Google, or waiting for Microsoft's marketplace to mature. It just requires an honest inventory, done once, updated as your content changes. Publishers who've already done this work will be ready the moment any of these payment rails becomes standard practice instead of an experiment. Publishers who haven't will be negotiating from scratch, under pressure, on someone else's timeline.
The web has run on an unspoken deal for three decades. Crawlers took content, and in exchange, they sent readers. That deal is fraying for a category of crawler that never sends anyone anywhere. What replaces it isn't going to be one universal standard handed down by Google, Cloudflare, or Microsoft. It's going to be whatever terms individual publishers are prepared to negotiate for themselves, and the ones who've already sorted out what their content is worth will be negotiating from a much stronger position than the ones still waiting to see what everyone else decides.


